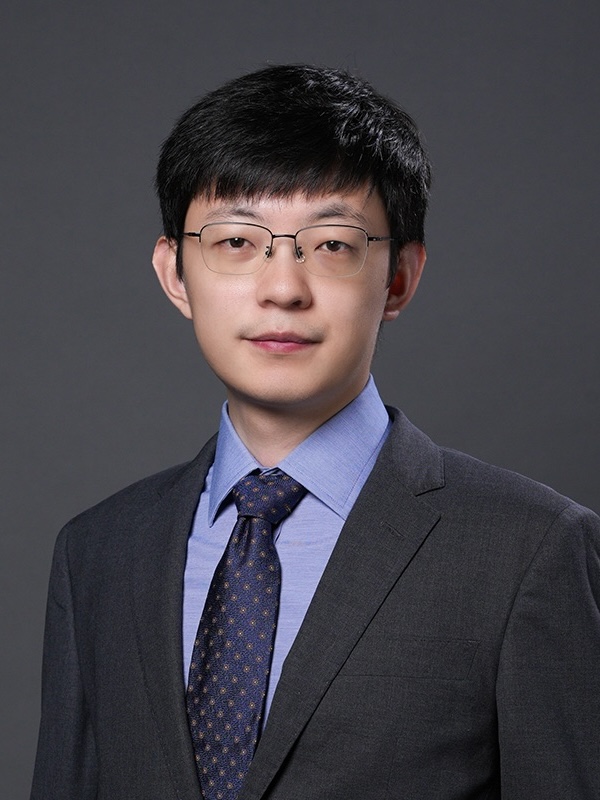
Xianhao Chen
The University of Hong Kong, Hong Kong SAR, China
Xianhao Chen is an assistant professor at the Department of Electrical and Computer Engineering, the University of Hong Kong, where he directs the Wireless Information & Intelligence (WILL) Lab. Prior to this, he received a Ph.D. degree in electrical and computer engineering from the University of Florida in 2022. He serves on the editorial boards of several flagship journals, including IEEE Transactions on Networking, IEEE Transactions on Wireless Communications, and ACM Computing Surveys. He received the Early Career Award from the Research Grants Council (RGC) of Hong Kong in 2024. His research interests include edge intelligence, machine learning, and wireless networks.
While edge devices like commercial smartphones can now run inference with on-device large language models (LLMs), enabling on-device fine-tuning of LLMs remains a formidable challenge. Addressing this challenge is vital for democratizing on-device LLMs in numerous privacy-sensitive domains such as agentic AI, mobile health, and home robots. In this talk, I will introduce our work on hybrid-order learning. Traditionally, first-order (FO) optimization via backpropagation demands substantial memory, whereas zeroth-order (ZO) optimization suffers from severe convergence slowdown. Therefore, neither of them is ideal for edge devices. To resolve this dilemma, we introduce hybrid-order (HO) learning that seamlessly combines both, which trains a model’s top segment with FO optimization while confining ZO optimization to its bottom segment only. Importantly, each device can flexibly select its order boundary according to its resource constraints. I will introduce two important paradigms of hybrid-order learning in distributed settings, i.e., hybrid-order federated learning (HO-FL) and hybrid-order split federated learning (HO-SFL), and articulate how these schemes enable LLM fine-tuning over resource-constrained, heterogeneous edge devices.