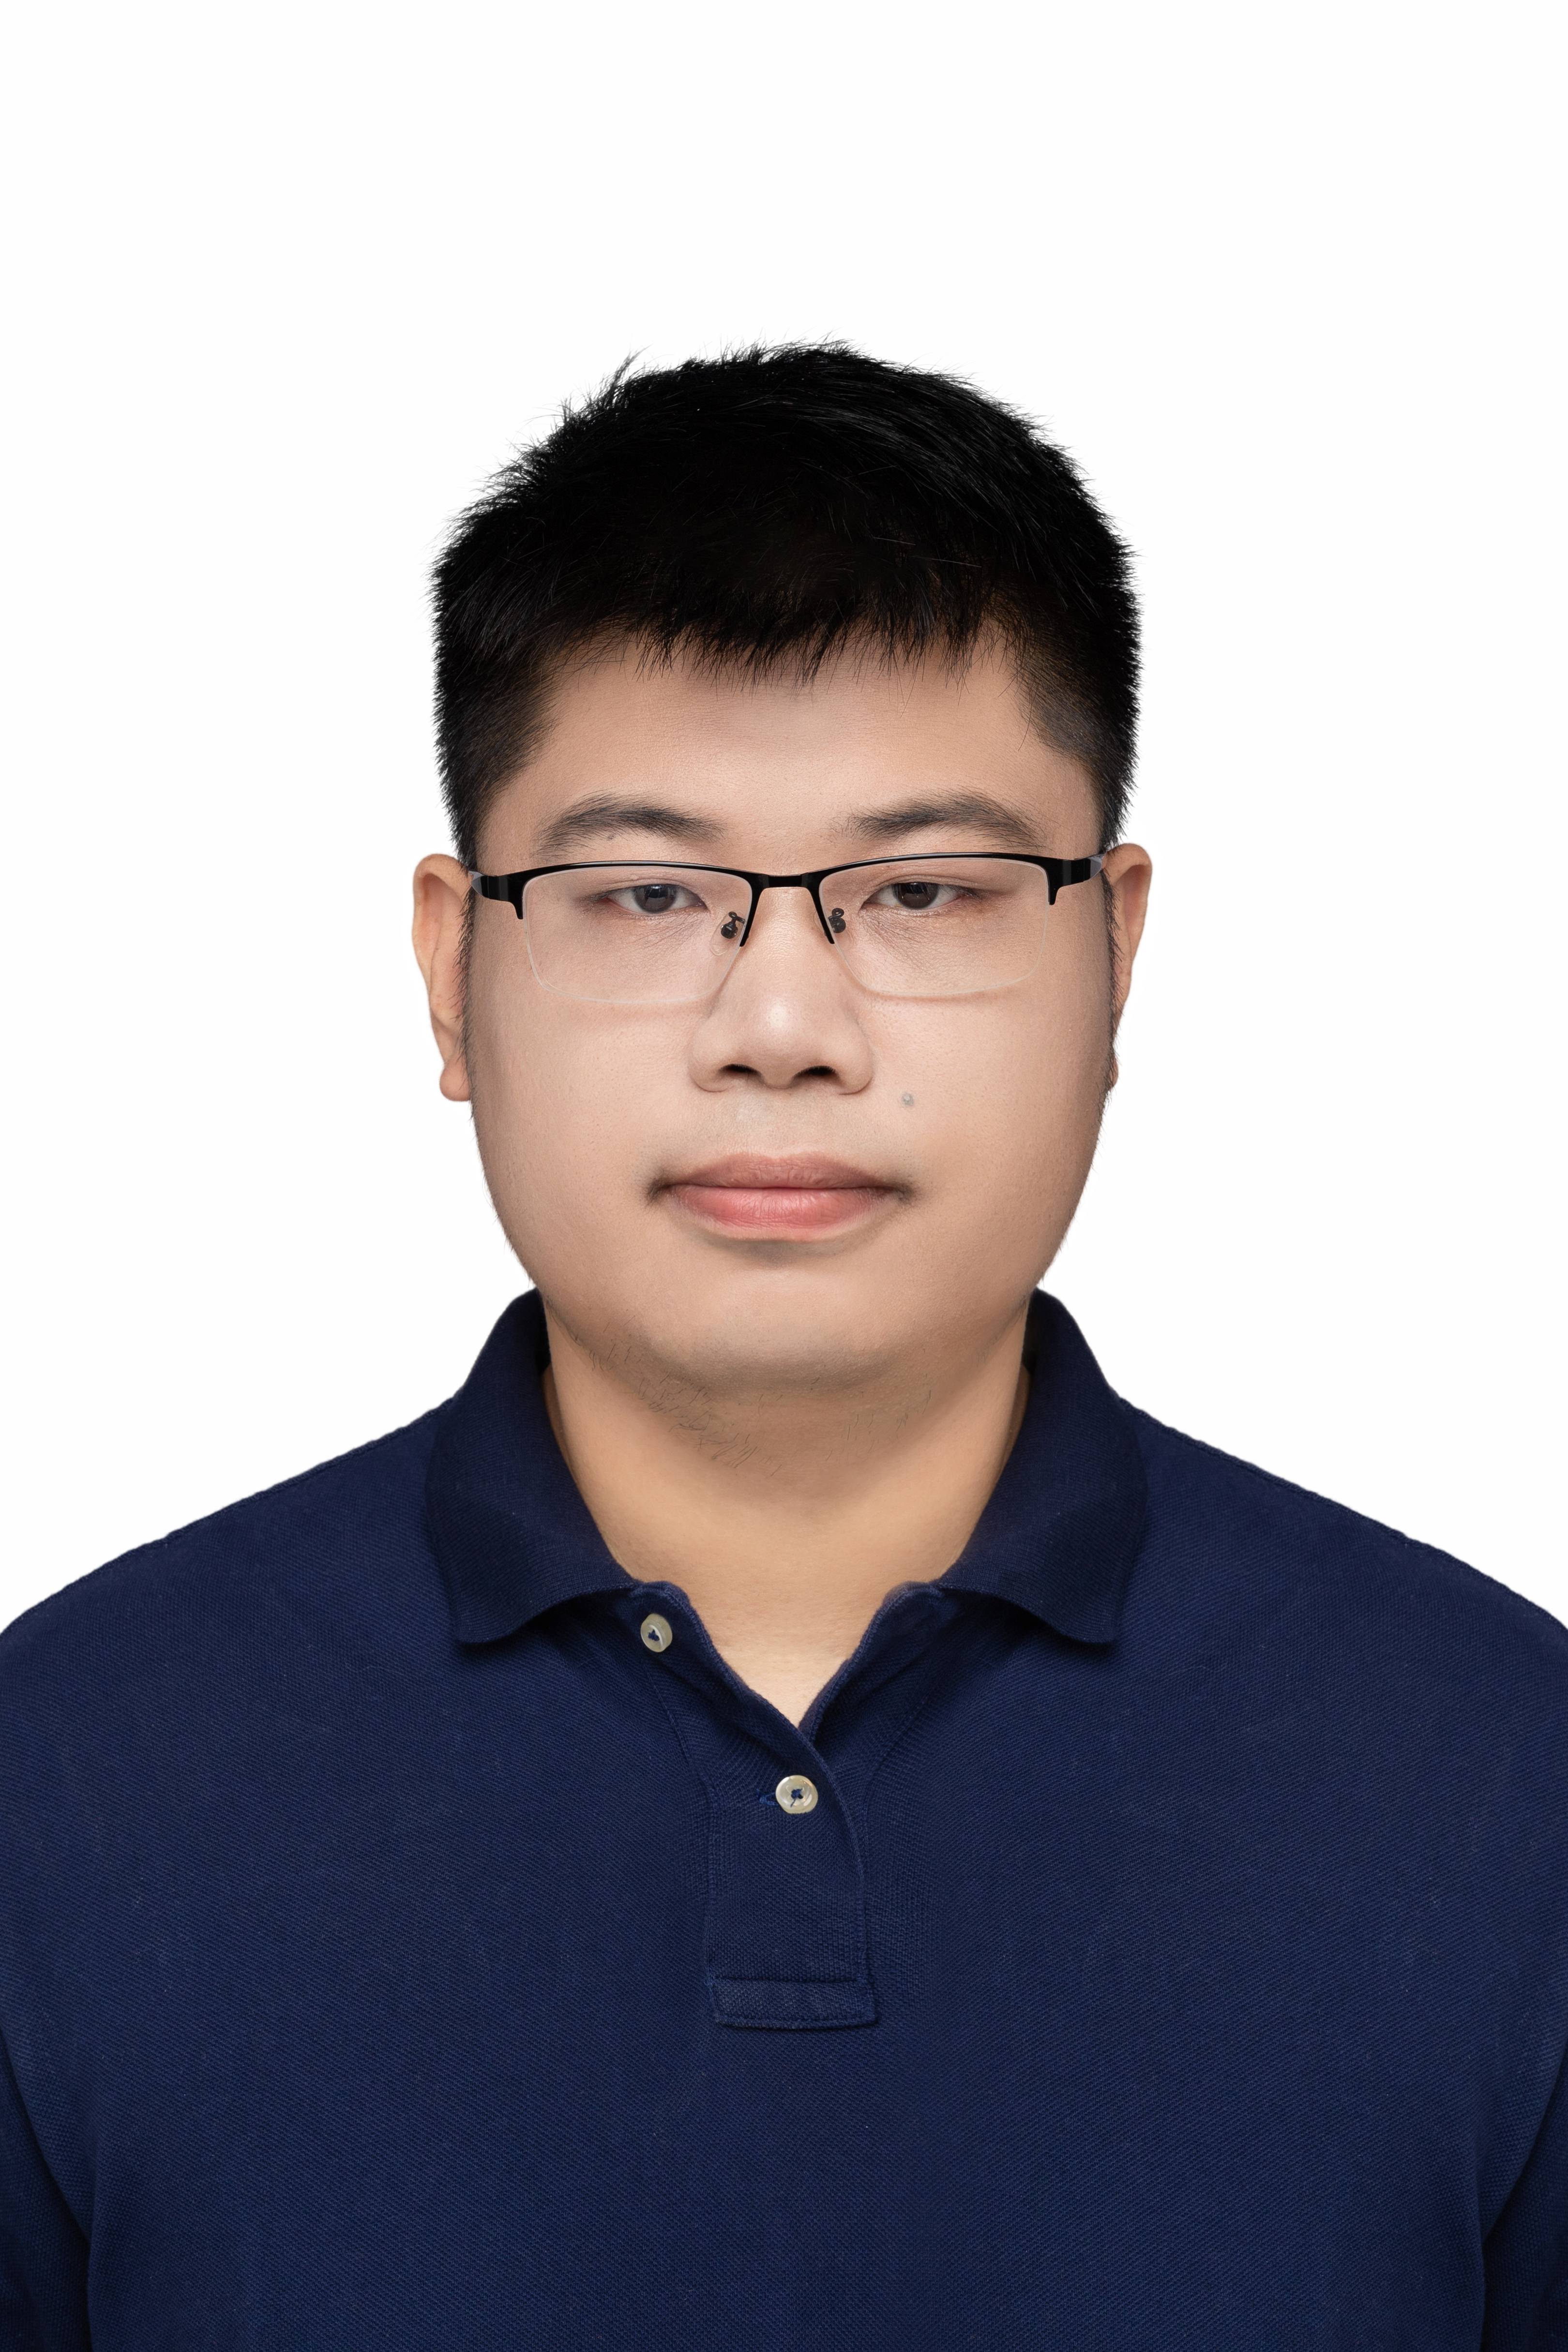
Tong Zhang
Harbin Institute of Technology, Shenzhen, China
Tong Zhang received the B.S. degree from Northwest University, Xi'an, China, in 2012, the M.S. degree from Beijing University of Posts and Telecommunications, Beijing, China, in 2015, and the Ph.D. degree in electronic engineering from The Chinese University of Hong Kong, Hong Kong, in 2020. He was a Post-Doctoral Fellow with the Southern University of Science and Technology from 2020 to 2022. He was a Lecturer with the Department of Electronic Engineering, Jinan University. He is currently an Assistant Professor with Harbin Institute of Technology, Shenzhen. His research interests include fluid antenna systems and reinforcement learning.
Fluid antenna system (FAS) revolutionizes wireless communications via utilizing position-flexible antennas that dynamically optimize channel conditions and mitigate multipath fading. This innovation is particularly valuable in indoor environments, in which signal propagation is severely degraded due to structural obstructions and complex multipath reflections. In this paper, we investigate the channel modeling and the joint optimization of antenna positioning, beamforming, and power allocation for indoor FAS. In particular, we propose a layout-specific channel model, and employ the novel group relative policy optimization (GRPO) algorithm for tackling the optimization problem. Compared to the state-of-the-art Sionna model, our model achieves an 83.3% reduction in computation time with an approximately 3 dB increase in root-mean-square error (RMSE). When simplified to a two-ray model, our model allows for a closed-form antenna position solution with near-optimal performance. For the joint optimization problem, our GRPO algorithm outperforms proximal policy optimization (PPO) and other baselines in sum-rate, while requiring only 50.8% computational resources of PPO, thanks to its group advantage estimation. Simulation results show that increasing either the group size or trajectory length in GRPO does not yield significant improvements in sum-rate, suggesting that these parameters can be selected conservatively without sacrificing performance.